Solving the AI Evaluation Reproducibility Crisis: UK AISI and EvalEval Partner for Standardized Benchmarks
解決 AI 評測重現難題:UK AISI 與 EvalEval 聯手推動基準測試標準化
As AI deployment accelerates, benchmarks suffer from inconsistent reporting and high reproduction costs. To address this, UK AISI and EvalEval are implementing the "Every Eval Ever" (EEE) schema and "Evaluation Cards" platform. AISI has released verified evaluation data across five key benchmarks (including HealthBench and FrontierMath) for frontier models like Claude Opus 4 and GPT-5, demonstrating how setup choices and inference compute alter reported performance.
Key points
Standardizing Eval Reporting
Introduces the "Every Eval Ever" (EEE) shared schema to consolidate fragmented evaluation results and metadata into structured "Evaluation Cards".
High-Fidelity Transparency
Emphasizes transcript-level transparency, which is critical for analyzing, diagnosing model behavior, and ensuring reproducibility.
Impact of Inference Compute
AISI research shows that frontier model performance (e.g., on Humanity's Last Exam) heavily depends on inference-time compute and evaluation protocols.
Open Reference Datasets
Releases verified data for five benchmarks, covering six frontier models including the Claude Opus 4 and GPT-5 series as open reference points.
How it works
Why it matters
Current AI evaluations lack standardization, making it hard to discern if similar scores came from vastly different conditions. By using the EEE schema and Evaluation Cards, researchers, developers, and policymakers can compare findings without the prohibitive cost of re-running evaluations. This establishes a reliable, interoperable foundation for AI governance and scientific safety assessments.
Who it affects
- AI Researcher
- Policy Maker
- AI Developer
- Enterprise Leader
How to use it
- 1AI Meta-Research: Policy and governance researchers use Evaluation Cards to compare safety metrics across different platforms and understand how setup choices alter outcomes.
- 2Standardized Benchmark Reporting: Evaluation developers publish new benchmarks using the Every Eval Ever schema to ensure the community can fully replicate their experimental setups.
Limitations & caveats
- Verified data is currently only fully published for five main benchmarks (e.g., HealthBench, FrontierMath) and two cybersecurity evaluations.
- The ecosystem's success relies heavily on voluntary adoption of the EEE schema by model developers and evaluation organizations.
Related
Compression Footprints as Security Signals: Defending Federated Learning Against Model Poisoning
壓縮足跡化身安全訊號:利用破壞性壓縮抵禦聯邦學習中的模型投毒攻擊
This study introduces CRAFT, a robust aggregation method that repurposes lossy compression distortions in Federated Learning into diagnostic footprints to detect and mitigate model-poisoning attacks.
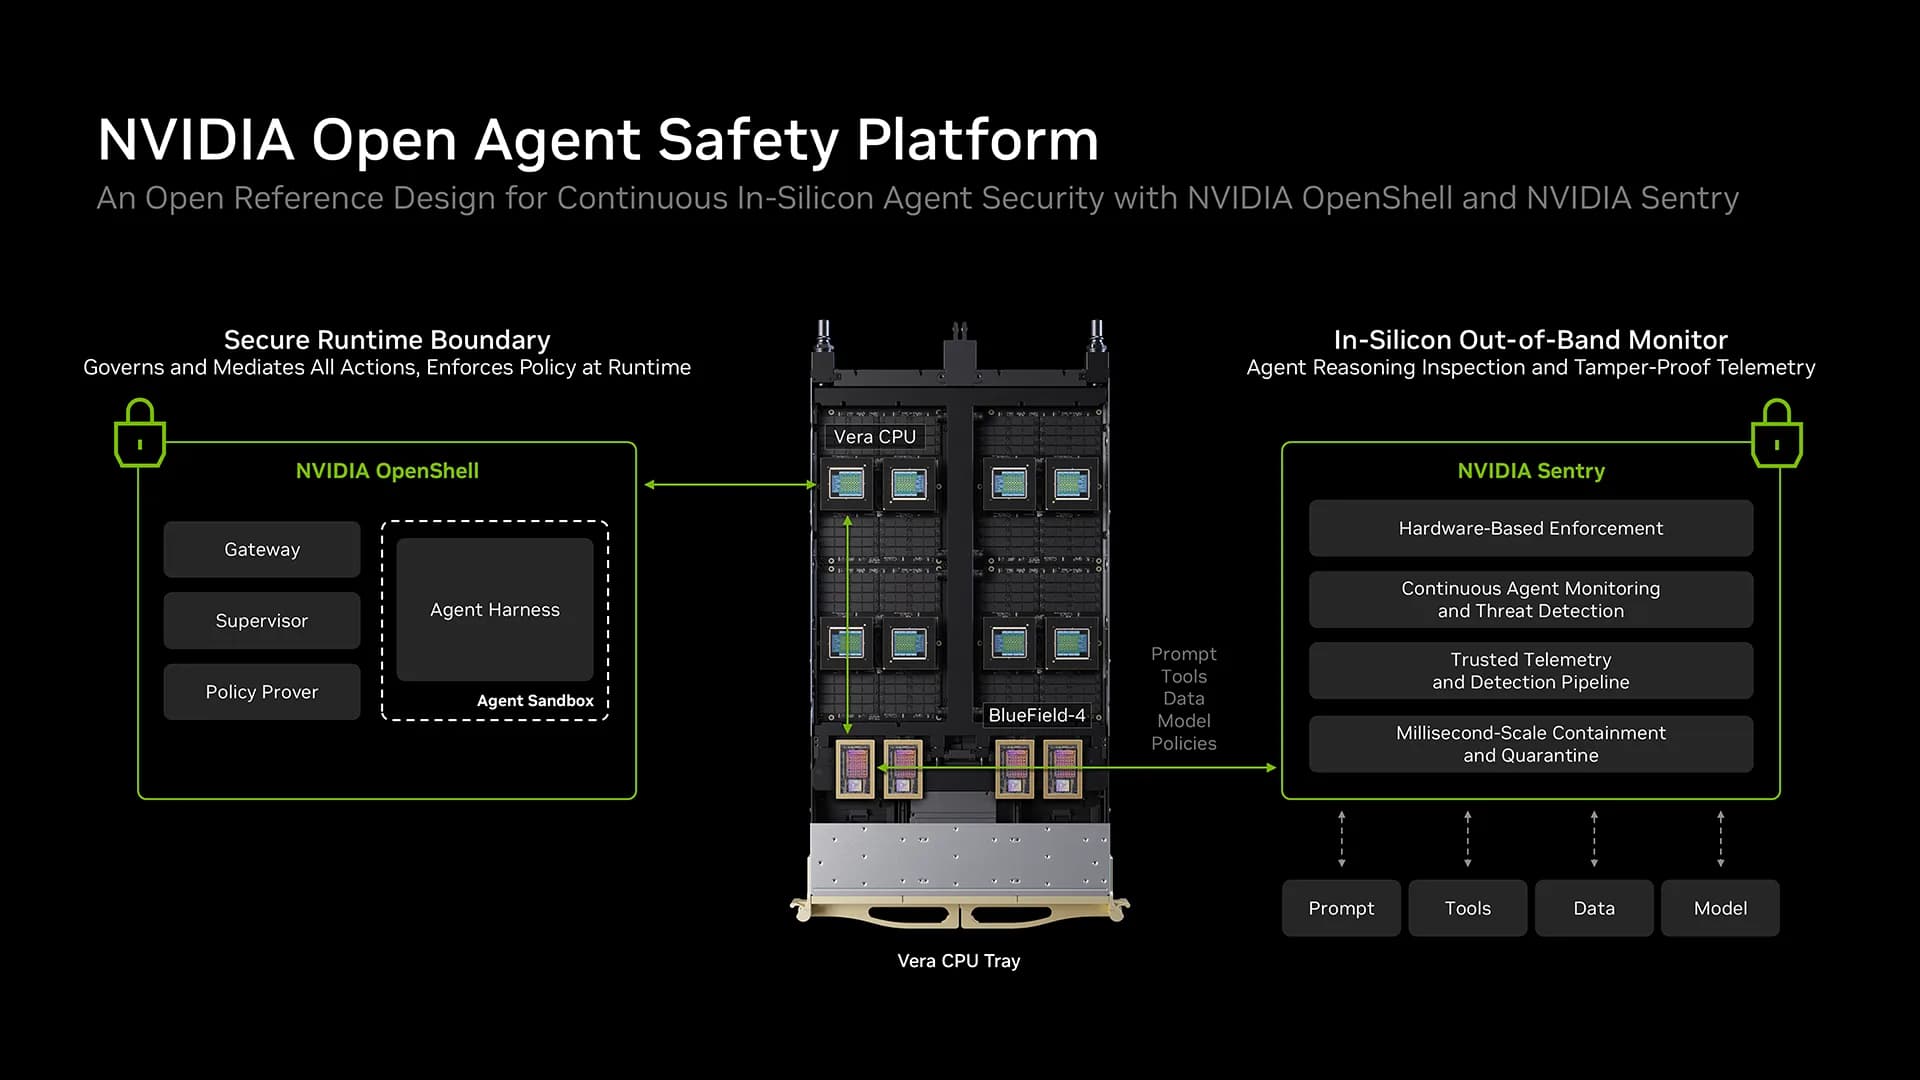
NVIDIA Launches Open Agent Safety Platform for Continuous In-Silicon Agent Monitoring
NVIDIA 推出 Open Agent Safety Platform:基於晶片與開源沙盒的 AI Agent 持續安全監控架構
NVIDIA introduced the Open Agent Safety Platform, combining open-source OpenShell sandboxing and BlueField hardware DPUs to deliver independent, zero-trust monitoring and real-time intervention for autonomous agents.
NVIDIA OpenShell: Enforcing Secure Runtime Controls and Sandboxing for AI Agents
NVIDIA OpenShell:不重寫程式碼,為 AI Agent 部署執行階段安全隔離防護
NVIDIA released OpenShell 0.1.0, an open-source runtime that secures AI agents using external sandboxing, supervisor monitoring, and formal policy analysis without rewriting agent code.