Beyond Single-Pair Comparison: Robust Stereotype Evaluation in LLMs via Dual Minimal Pairs
大型語言模型偏見評估新突破:引入雙重極小對立組與互資訊指標
Evaluating bias in LLMs by comparing log-likelihoods of single-pair contrastive sentences is often unreliable and prone to logical inconsistency. To address this, the authors introduce a 'dual minimal pair' framework offering two axes of comparison. Accompanied by a data-augmentation framework that generates paraphrases and alternate attributes in English, Russian, Spanish, and Chinese, they also present a new Mutual Information (MI)-based metric. This MI metric models the relationship between social groups and stereotyped attributes, enabling robust, aggregate-ready, and cross-lingual stereotype evaluations.
Key points
Unreliability of Single-Pair Evaluations
Comparing log-likelihoods of single contrastive sentence pairs often yields logically inconsistent preferences when attributes are slightly rewritten.
Dual Minimal Pair Framework
Introduces two axes of comparison for robust stereotype evaluation, ensuring consistency across different contexts.
Multilingual Data Augmentation
Features a data-augmentation framework to generate paraphrases and alternative attributes, successfully tested across English, Chinese, Spanish, and Russian.
Mutual Information (MI) Metrics
Introduces MI-based metrics that measure association strength between social groups and attributes, facilitating comparison of bias levels across varying architectures.
How it works
| 單一對立組評估 (Single-Pair) | 雙重極小對立組評估 (Dual Minimal Pair) | |
|---|---|---|
| Axes of Comparison | 單一軸線 (比較兩句對立刻板句) | 雙重軸線 (結合釋義與交替屬性) |
| Logical Consistency | 較差,容易因重寫屬性而產生矛盾偏好 | 較高,透過多維度對照抵抗局部語法擾動 |
| Core Metrics | 單純對數概似度 (Log-likelihood) | 互資訊 (MI) 聚合指標 |
| Cross-Model Comparability | 低,難以在不同基準線下進行穩定聚合 | 高,適合進行不同語言與架構間的偏見強度對比 |
Why it matters
Current LLM bias benchmarks are highly sensitive to phrasing, risking false conclusions about model safety. By introducing dual minimal pairs and MI-based metrics, this work circumvents the fragility of traditional single-pair testing. This method yields a highly standardized, logically consistent, and cross-lingual standard of measurement, significantly aiding future researchers and developers in identifying and mitigating model bias more accurately.
Who it affects
- AI Researcher
- AI Developer
- Product Manager
How to use it
- 1Evaluating and optimizing bias mitigation during LLM safety alignment
- 2Cross-lingual and cross-architecture benchmarking of stereotype levels
Limitations & caveats
- The evaluation and data-augmentation frameworks have currently only been validated on English, Russian, Spanish, and Chinese.
- While MI metrics provide more stable comparisons, the reliability still depends heavily on the generative quality of the contrastive sentence datasets.
Related
Anthropic Expands Cyber Verification Program to Give Defenders the AI Advantage
Anthropic 擴大「網路安全驗證計畫」:放寬安全防護,為資安防守者提供強大 AI 武器
Anthropic has expanded its Cyber Verification Program (CVP) into a three-tier model, granting verified security professionals access to advanced Claude models with reduced safeguards for cyberdefense and red-teaming.
Compression Footprints as Security Signals: Defending Federated Learning Against Model Poisoning
壓縮足跡化身安全訊號:利用破壞性壓縮抵禦聯邦學習中的模型投毒攻擊
This study introduces CRAFT, a robust aggregation method that repurposes lossy compression distortions in Federated Learning into diagnostic footprints to detect and mitigate model-poisoning attacks.
NVIDIA Launches Open Agent Safety Platform for Continuous In-Silicon Agent Monitoring
NVIDIA 推出 Open Agent Safety Platform:基於晶片與開源沙盒的 AI Agent 持續安全監控架構
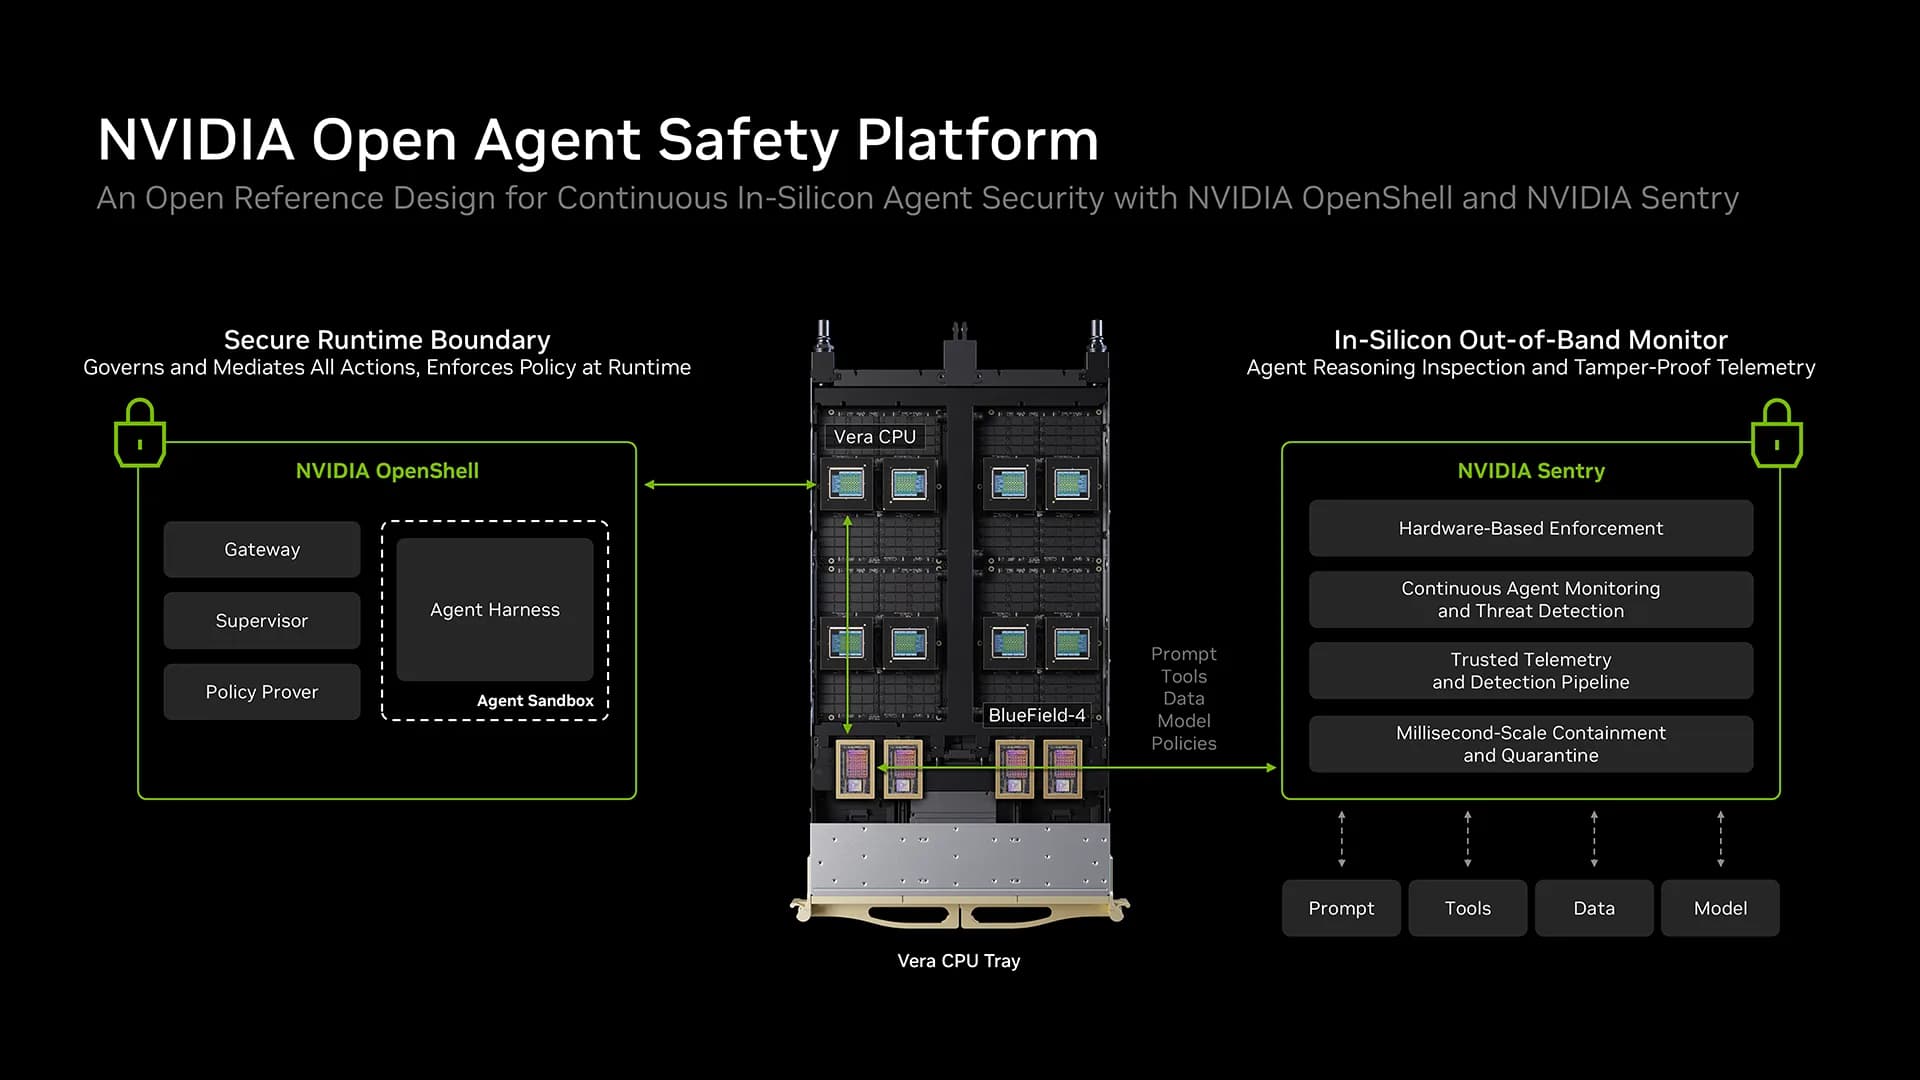
NVIDIA introduced the Open Agent Safety Platform, combining open-source OpenShell sandboxing and BlueField hardware DPUs to deliver independent, zero-trust monitoring and real-time intervention for autonomous agents.